Wednesday, April 02, 2014

HIMSS14 and the Culture of Interoperability


Interesting follow up piece to HIMSS14 from Deloitte in WSJ, and a few thoughts on human and machine interoperability. The message:

Interoperability standards are often overemphasized in discussions of data sharing, and it is important to understand that standards for interoperability already exist and can be implemented. What is critical is shedding the light on building interoperability into vendor design of medical products versus just building standards. Enlisting provider buy-in is one way of supporting this goal.
 
We have the standards, now we need to apply them. For modern interoperability standards like HL7 CDA, for instance, the barrier to entry is incredibly low – you can wrap an existing PDF in an appropriate header, which is essentially boilerplate, and you have satisfied the lowest level of CDA compliance. What is important to understand here is that “clinical interoperability” does not have to imply “machine-readable” except in the broad sense of syntactically capable of exchange between two systems or components. The lowest level of interoperability is exchange of human-readable content within a structure that can later be extended to support machine-readable coding. 

From the HL7 Standards blog:

The primary characteristic of a CDA document is that it must be readable by humans. The CDA specification states that, “human readability guarantees that a receiver of a CDA document can algorithmically display the clinical content of the note on a standard Web browser.” This requirement means that a clinician or patient can take a CDA document and display it on any computer with a web browser without the need to load any additional application.

The real work in interoperability, as we know, is in rationalizing and aligning code-sets. That's a governance issue. Exposing human-readable content in a structured fashion is important, as described above. But is it possible to access a system's supported vocabulary  and conformance profile using a standard Web browser? Maybe that would be useful as well. Incidentally, that's one of the ways FHIR goes beyond CDA. Clinical interoperability is about exchanging a specific type of information, for instance, exchanging clinical information about a patient that allows an exchange partner to leverage what we already know about them. One of the things we should be able to exchange is a conformance profile that defines how such an exchange can take place.

This is at the heart of an ongoing debate in Canada about the future of both CDA and SNOMED-CT. We have existing standards and terminology sets, so aren't these adequate to the task? What can we learn from this debate about what factors contribute to the success or failure of clinical interoperability projects? How can we reduce complexity, while increasing availability of information and metadata?

Thursday, March 27, 2014

Architecture of Participation in Healthcare

In general, I have a lot of positive things to say about HL7 FHIR, an emerging healthcare standard with deep roots in both Web-oriented Architecture (WOA) and the HL7 Reference Information Model (RIM). Along with a focus on REST, URLs, granularity and so forth, one idea that typifies WOA is a term coined by Tim O'Reilly back in 2004, the Architecture of Participation, in which he describes the participatory nature of the Worldwide Web, which was successful because it expanded participation in technology and information sharing far beyond the insular community of software developers. It worked because participation was expanded to include anyone. And this is important because without participation, there can be no success.

You may ask, can you apply this principle of Architecture of Participation to Healthcare? Good question, and I think this is where the "a-ha" moment comes in, and why when people start to think about HL7 FHIR, they kick themselves and say "well, it's about time," because the fact is, the Architecture of Participation is built right into the RIM: first day on the job with  HL7, someone hands you a primer and explains that it's very simple, the RIM describes Entities in Roles Participating in Acts.  These are the RIM base classes, and it's right there in the centre: Participation. HL7 describes clinical workflow, and workflow is performance. It is Entities and it is Acts, and the associations between these are mediated by Roles.

And there in the middle is Architecture of Participation.

View Source. Blue Button. Ten years' worth of knowledge in the RIM. Which is why I am excited for the next ten years.

Saturday, March 22, 2014

Object-oriented JavaScript as a language for learning

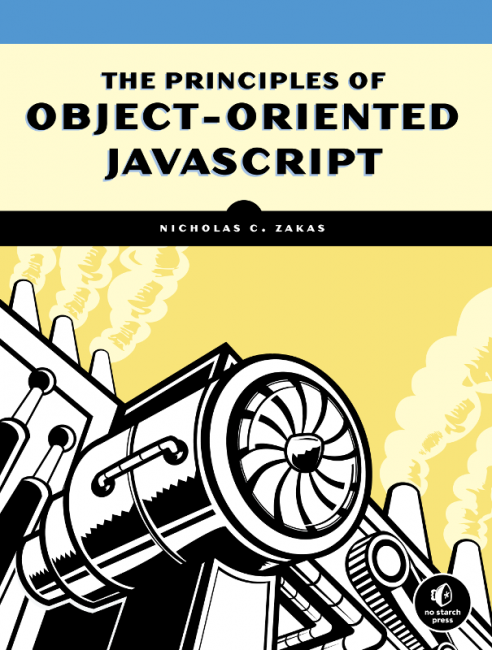
I have been reading Nicholas Zakas' Principles of Object-oriented JavaScript, from No Starch Press. I have been using JavaScript for many years, and to this point, the books I have found most useful are the essential "rhino" guide and Doug Crockford's "Good Parts," both from O'Reilly, because they were the books that first turned me onto the awesome potential of JavaScript as a declarative language that also supports inheritance, and then steered me away from the dangers of some of the patterns and habits into which I had fallen.

Zakas writes well - this is not his first book - and I love the way this book is organized around well thought out descriptions of core ideas; for instance, what is an Own Property, and why would you need one, or how does the Prototype Chain actually work. This is a quick read that really provides you with everything you need to then move onto a framework specific book on Backbone or Angular, whatever you need for your particular project; and really this is where this book shines, when it digs down into some of the more esoteric features of the JavaScript language, but never leaves stops answering the question, when is this going to be important when I am writing actual code. This is the book I would recommend, for instance, to any of my colleagues who is making the transition from server-side Java to client-side JavaScript. Quite simply, Zakas answers the questions you are going to ask with well though out answers.


Beyond this, all the books I have seen from No Starch Press are beautiful to look at. My own background is in Literary Theory in addition to Information Technology, and I loved my graphic novel guides to Derrida, Foucault and Freud, so much so that I gave them all away to people who wanted to know more about what I was studying. Like those graphic novels, I imagine the books from No Starch Press are a delight to give away; they look great. In addition to the aforementioned Java programmer colleagues, I also think Zakas' book would be very apt for a 15 or 16 year old who is interested in programming, as would any number of No Starch's "manga guides".

In short, good code examples, short chapters, great discussion in depth of core ideas with well
thought out descriptions of the things that make object-oriented JavaScript idiosycratic, and a book I find myself going back to and recommending for others, particularly people I know will be going on to use JavaScript with framework support like Angular.

Thursday, March 13, 2014

HL7 FHIR Questionnaire resource

I have found David Hay's posts on the HL7 FHIR Questionnaire resource indispensable. One thing I find especially exciting is how with FHIR you can build a server API that supports XML and JSON, completely within the standard, then work with whichever is appropriate. You can also build a simple application that, for instance, publishes a read-only Questionnaire, and if at some time in the future you need to persist survey responses, the FHIR resource already supports that. It's a particularly agile standard in this respect.

Monday, February 03, 2014

Sozi for Inkscape: SVG as Presentation Web

I started out using PowerPoint, and it was good. I perfected the six slide presentation. I discovered Prezi, and it was... interesting. I like the idea of a non-linear presentation which focuses in and out and slides around to make its point. And I like being able to quickly make a presentation that tells a compelling story without having to move from left to right.

And then, to quote Upworthy, I found the Sozi plugin for Inkscape, and it blew my mind.

So okay, you need to be handy with vector graphics (SVG) if you want to make a professional looking poster using Inkscape. And you have to be careful, I discovered, about using free-flowing text, which just plain doesn't show up in Sozi. But, it's easy to find nice examples of people who have already made professional looking posters using Inkscape, and it's easy to "Convert to Text" to fix free-flowing text, and it is so easy to use the Sozi plugin to sequence frames and create an amazing looking presentation that will impress your boss.

But more than this, I have recently discovered that you can use Inkscape to embed links - internal and external - within an SVG document, so really, as far as I can tell, there are two kinds of websites you should be thinking about: One built on the idea of application, as in single page application, or server-side templated application or whatever, but definitely HTML5; and one built on the idea of presentation. And for a presentation website, why not just use SVG, using Inkscape and Sozi as a development tool? Really. Why not?
I'm reading Nicholas Zakas book on Principles of Object-Oriented JavaScript (No Starch Press), and I'm really enjoying it. When you I first encountered JavaScript, I found it very functional, in the sense that I could make it do things I wanted it to quickly and easily, a trait which I had never found in Java. Then I read more on the web, and then I found Crockford and Resig and the important JavaScript books they wrote, and it started to make more sense. Where books like The Good Parts are prescriptive, because they have to be, and JavaScript is a language with clearly too much rope, that is not the mode of Zakas book. Instead, the approach here is to make clear statements about what makes JavaScript work - what makes it special - and the explanation here is an ideal mix of theory and practice, equally useful for the web developer seeking a better academic understanding of the language and for the classically trained C# or Java developer making sense of JavaScript's idiosyncrasies. Highly recommended as a companion to The Good Parts.

For instance, this kind of description is very concise:
Reference types represent objects in JavaScript and are the closest things to classes that you will find in the language. Reference values are instances of reference types and are synonymous with objects (the rest of this chapter refers to reference values simply as objects). An object is an unordered list of properties consisting of a name (always a string) and a value. When the value of a property is a function, it is called a method. Functions themselves are actually reference values in JavaScript, so there’s little difference between a property that contains an array and one that contains a function except that a function can be executed.
And of course, it is this concision that I appreciate here.

Wednesday, January 01, 2014

Liquid XML 2014 Beta

For the last couple months I have been using a beta version of Liquid XML, for a number of reasons. I have a laptop, and I find Liquid a little easier to use on a smaller screen than XML Spy or Oxygen, and I have found the support for XML Schemas 1.1 very useful. This is new to 2014, but has been available in XML Spy and Oxygen for a while.

Hopefully XSD 1.1 becomes mainstream. It's just such a complete improvement over XSD 1.0.

With Liquid XML, I can also flatten composite schemas. I have been doing this using CAM Processor, and it's not something I need to do very often; and more often than not, I just roll my own transform for this. Still, it's useful. In the coming year, we are going to see a continuing shift from XML to JSON technologies on both the client and server, but I think this is misleading. At the same time, server-side XML is reaching a renaissance, because server-side validation and transformation are a critical part of client-side delivery of conformant JSON. It's as simple as that.

XPath is the power behind XQuery, XSLT, OASIS CAM and ISO Schematron. Now, it's an important part of XML Schemas; and XPath is developing very quickly, considering most people who are using XPath are still using version 1.0, and yet there are very mature features coming in version 3.0 - so it's still a good time to be working with XML; and it's a great time to be working with JSON as well.

Tuesday, December 31, 2013

Using XSD 1.1 with HL7 as a Schematron replacement

Several years ago, I posted an article on IBM developerWorks about using OASIS CAM and David Webber's CAM Processor tooling to extend HL7 v3 schemas to better handle the extra conformance levels required by the HL7 RIM, particularly dealing with null flavors. At that time, CAM Processor was relatively new, and CAM is now reaching a very good level of maturity in the NIEM community; however, I suspect that HL7 specifications will always be more demanding than NIEM, in part due to the complexities of the RIM. The best alternative has always proven to be XSD 1.0 + ISO Schematron. At the time, I had considered using XSD 1.1, which provides assertions, but at the time, XSD 1.1 was still in development, and the CAM tooling just worked.

Recently however, it dawned on me that XSD 1.1 is now a W3C Recommend, and it has evolved, much like CAM, to include features that originated in Schematron. Actually these ideas didn't originate in Schematron, but that's another story.

As opposed to OASIS CAM, which really combines the core strengths from Examplotron and Schematron - using a reduced instance XML instead of a hierarchical grammar, and using XPath to define assertions - XSD 1.1 retains the hierarchical grammar, adding Schematron-like assertions to the extension/restriction process which is already built into XSD. So, to test data-type assertions on an element, you restrict the type definition for the element; to test conformance assertions on an element, you extend the type of the element to include any necessary assertions.

For example, in the HL7 RIM, an element can be Optional, Required or Mandatory - with an extra level, Populated, in some realms. For Optional, Required or Populated elements, a nullFlavor attribute is permitted in place of absent valued information, to describe why the information was absent. The phrase null flavor is confusing, but really it's just a reason why the information is absent. For Mandatory elements the nullFlavor attribute is forbidden.

In an existing XSD schema, you can determine which elements are Mandatory because they have minOccurs which is greater than 0, and isMandatory is true [ed. this has been edited]:
<xs:element name="processingCode" type="CS.CA"
   minOccurs="1" maxOccurs="1">
   <xs:annotation>
      <xs:appinfo>
         <mif:attribute name="processingCode"
             minimumMultiplicity="1" maximumMultiplicity="1"
             isMandatory="true" isImmutable="false">
            <mif:businessName name="D:Processing Code"/>
            <mif:annotations>
                <mif:appInfo>
                    <mif:mapping sourceName="Sample">
                        <mif:text>
                            <mif:p>[MSH-11.1]</mif:p>
                        </mif:text>
                    </mif:mapping>
                </mif:appInfo>
            </mif:annotations>
            <mif:type name="CS.CA"/>
            <mif:vocabulary>
                <mif:conceptDomain name="ProcessingID"/>
            </mif:vocabulary>
         </mif:attribute>
      </xs:appinfo>
   </xs:annotation>
</xs:element>
In order to add an assertion using the new features in XSD 1.1, we need to remove the type attribute from the element, and extend it as a complex type:
<xs:element name="processingCode" type="CS.CA"
   minOccurs="1" maxOccurs="1">
   <xs:annotation>
      <xs:appinfo>
         <mif:attribute name="processingCode"
             minimumMultiplicity="1" maximumMultiplicity="1"
             isMandatory="true" isImmutable="false">
            <mif:businessName name="D:Processing Code"/>
                    . . .
            <mif:type name="CS.CA"/>
            <mif:vocabulary>
                <mif:conceptDomain name="ProcessingID"/>
            </mif:vocabulary>
         </mif:attribute>
      </xs:appinfo>
   </xs:annotation>
   <xs:complexType>
      <xs:complexContent>
         <xs:extension base="CS.CA">
            <xs:assert test="not(@nullFlavor)"/>
         </xs:extension>
      </xs:complexContent>
   </xs:complexType>
</xs:element>
If additional assertions are required, they can be added to the same extension; however, in this case, the only assertion we require is to ensure that the Mandatory element does not have a null flavor when we validate an instance message. All that remains now is to change our XML editor so that it is using Xerces 2.11.0 or higher, which supports XSD 1.1, and when we validate a message, we will be alerted if there is a processingCode element which is null flavored.

Sunday, December 29, 2013

Wednesday, October 23, 2013

My New Policy for the Internet

I am drafting up my new policy for the internet. It consists of three ideas, nothing new, but possibly newly articulated as a haiku or something:

#thinkbeforeyoulink
#carebeforeyoushare
#waitbeforeyouhate

And most likely, don't +1 anything. 

Wednesday, August 14, 2013

DB2-RDF

I still think this is really cool. NoSQL Graph support for DB2-RDF holds a lot of promise, particularly if it performs as well with large data sets as people are suggesting it does.

Summary:
1.  DB2-RDF support is officially called "NoSQL Graph Support". 
2.  The API extends the Jena API (Graph layer).  Developers familiar with Jena TDB will have the Model layer capabilities they are accustomed to.
3.  Although the DB2-RDF functionality is being released with DB2 LUW 10.1, it is also compatible with DB2 9.7.
4.  Full supports for SPARQL 1.0 and a subset of SPARQL 1.1.  Full SPARQL 1.1 support (which is still a W3C working draft) will be forthcoming.
5.  While RDBMS implementations of RDF graphs have typically been non-performant, that is not the case here*.  Some very impressive and innovative work has been put into optimization capabilities.  Out-of-the box performance is comparable with native triple stores, and read/write performance in the optimized schema has been seen to surpass these speeds.

Saturday, August 10, 2013

Angular Saxon Summer Update

My side project over the summer started with a premise: using Saxon-CE, the client-side port of the popular Saxon library, on a Firefox OS device. It didn't work on the Simulator, and I worked on some different Mobile Health work on PhoneGap and Android, and then one day, Saxon-CE just started working under both PhoneGap and Firefox OS. A new Simulator had come out, and the stars had aligned.

Firefox OS provides native support for Cross-Origin Resource Sharing (CORS) using XMLHttpResponse (XHR), as well as native support for JSON. I knew that I wanted to use XML, but I was finding JSON useful as well. About this time, I became involved with the Prescription Medication Information Exchange (PMIX) demo, which is part of David Webber's Open-XDX project, which is an extension of OASIS CAM. And it supports both JSON and XML endpoints. I had also been working with HL7 FHIR, which also supports REST, JSON and XML.

So at that point, I had a rudimentary XSLT view which ran as an application on Firefox OS, backed by Open-XDX. Not very useful, considering that Firefox OS devices had not at this point begun shipping commercially (they still haven't). So I turned my focus back to PhoneGap for Android. Without native support for CORS XHR, I needed JQuery and Backbone, and I started down that path; however, this didn't allow me to share code between PhoneGap and Firefox OS, since JQuery and Backbone were over-powered for what I wanted to accomplish.

Then I watched the AngularJS demo video. I had worked with Thymeleaf on the server-side, and the idea of attribute driven directives in the HTML seemed very natural. It is. I have no doubt that these directives will soon find their way into native support in browsers. Try it. It's practical magic, and it works. Better than JQuery, I feel, once you get used to it.

As I worked with these technologies, I started to have a feeling, and I am starting to see that it is more or less accurate: with planning, a common code base can be used with PhoneGap and Native Browser Mobile like ChromeOS and Firefox OS, using a Dependency Injection framework like AngularJS with a templating framework like Saxon-CE. More than this, Angular and JSON shine on PhoneGap, where you are contending with an existing VM, and Saxon-CE runs really slow; on Firefox OS, with native JavaScript, AngularJS is harder to work with and less necessary, and Saxon-CE performs well.

#AngularSaxon #AngularSummer

Tuesday, August 06, 2013

New Glue: Using Angular and CSS pseudo elements

My overall plan for Rhizome is to auto-schema-generate Views - partial HTML5 ng-includes - which I have bundled up as ordered lists, combined with CSS3 pseudo elements to inject in application labels, positioning of elements and so forth. The idea is that a change to the underlying schemas should require regeneration of the Views, but not of the application.

<ol id="prescriptions">
    <li ng-repeat="prescription in pmix.response.prescriptions">
        <div class="pmpPrescription">
            <span class="pmpPrescriptionNumberText" ng-bind="prescription['pmp:PrescriptionNumberText']"></span>
            <span class="pmpDrugRefillNumberCount" ng-bind="prescription['pmp:DrugRefillNumberCount']"></span>
            <span class="pmpPrescriptionFilledDate" ng-bind="prescription['pmp:PrescriptionFilledDate']['nc:Date']"></span>
        </div>

        <div ng-repeat="prescriptionDrug in prescription['pmp:PrescriptionDrug']">
            <div class="pmpPrescriptionDrug">
                <span ng-bind="prescriptionDrug['pmp:DrugProductNameText']"></span>
                <span ng-bind="prescriptionDrug['pmp:DrugStrengthText']"></span>
                <span ng-bind="prescriptionDrug['pmp:DrugUnitOfMeasureText']"></span>
            </div> 
        </div>
    </li>

</ol>

And then the corresponding stylesheet looks like:

/* Prescription resource labels: */
.pmpPrescription::before {

   content: "Prescription #: ";        
   font-weight: bold;
}
 

.pmpPrescriptionDrug::before { 
   content: "Prescription Drug: ";
   font-weight: bold; 
}

.pmpDrugRefillNumberCount::before { 

   content: "("; 
}
 

.pmpDrugRefillNumberCount::after { 
   content: " refills)"; 
} 

And the resulting screen looks like:

Prescription #:  RX-12453 (3 refills)
Prescription Drug: Hydrocet LOW 5MG

Resource-based Mobile Links:

http://www.dfki.de/~sonntag/ubicomm10.pdf
http://www.goodreads.com/book/show/16674717-the-agile-architecture-revolution
http://sharedservices.lnwprogram.org/sites/default/files/XJC_-_Art_of_the_Possible.pdf 

Monday, August 05, 2013

Strategy: Turning Theory into Practice

I have been reading The Strategy Book, by Max McKeown. This is a very short review because I haven't read the book fully yet, and because no approach to business strategy can be evaluated immediately. It takes time to implement business strategy, and it takes longer to evaluate success.\

On thing that strikes me, and perhaps this is because I am a consultant and implementer, not a business person, is that the strategy approach described is very active - "Strategy in Action" - which makes sense. But my personal strategy is very passive, or rather, responsive. It's not a right/wrong thing, but relates more to what you are trying to accomplish.

So when I read "Position, Intention, Direction", I can't disagree that these things are an important part of strategy. And then these criteria are described in terms of Objective, Context, Challenge and Success. This is fine-grained, but my own personal strategy, as I have described, is intentionally responsive:

Vision - what is the message you are creating or are hearing?
Precision - is your description of the problem-space accurate?
Concision - have you removed all the noise from your message?
Decision - can you act upon your vision?

So these are responsive criteria, with the last cutting over into active territory. Decision is where you cut over from "-ision" to "-ition".

Tuesday, July 30, 2013

Rhizome Business Value

Rhizome is a resource-based mobile demo I am building. It was originally intended for an HL7 FHIR connectathon to build out a security layer, and since developed into a companion to the PMIX Open-XDX API demo on VerifyXML.org, demonstrating using mobile JSON and XML.

Rhizome stands for "Resource-based Health Information Zone for the Mobile Enterprise"... the name is intended to be tongue in cheek, and the "R" could stand for REST, "E" for Exchange... but there is a buried meaning here as well: a rhizome like ginger or bamboo is diageotropic, meaning that it grows laterally; and the Rhizome application by design supports concepts like cross-jurisdictional exchange because it is resource- and scheme-based. It goes lateral.

In order to succeed in the enterprise, mobile exchange needs to be built on resource-based open web standards, which support making cross-jurisdictional data exchange work. This doesn't mean that the comprehensive approach taken by HL7 v3 is wrong, but we also need to support less complicated protocols like JSON and REST, using an agile approach towards content creation, consumption, collaboration and curation. Examples of this are projects like GreenCDA, HL7 FHIR and Open-XDX. Rhizome is an example of this also.

French literary theorists Gilles Deleuze and Felix Guattari introduce their A Thousand Plateaus by outlining the concept of the rhizome (quoted from A Thousand Plateaus):
  • 1 and 2: Principles of connection and heterogeneity: any point of a rhizome can be connected to any other, and must be
  • 3. Principle of multiplicity: only when the multiple is effectively treated as a substantive, "multiplicity" that it ceases to have any relation to the One
  • 4. Principle of asignifying rupture: a rhizome may be broken, but it will start up again on one of its old lines, or on new lines
  • 5 and 6: Principle of cartography and decalcomania: a rhizome is not amenable to any structural or generative model; it is a "map and not a tracing"

Structure within Angular

I am finding more useful resources for AngularJS, including Christopher Hiller's Developing an AngularJS Edge (Bleeding Edge). What I am going to do here is describe the structure I have come to after a lot of refactoring in my Rhizome application, using AngularJS and Saxon-CE. It's not perfect,  but I do want to document it at this point. I'm using PhoneGap, so this all resides in assets/www:

lib/shared - contains the JavaScript files for AngularJS and Saxon-CE
lib/rhizome/css - contains rhizome.css, references to Gaia css
lib/rhizome/js - contains Controllers.js, PresentationServices.js
res/views/html - contains pmixRequest.html, pmixResponse.html
res/views/xslt - contains PMPPrescriptionReport-application.xslt, other stylesheets

The stylesheets still need some work - I started out building a pure Gaia application for Firefox OS, before porting into PhoneGap for Android, but I have retained some of the Gaia look and feel. I am also considering leveraging AngularUI/Bootstrap for this purpose.

All of my controllers are in a single file, and align nicely with my views. The Presentation Services contains my rendering service and Business Services is currently empty. I am sure I will require some business logic eventually. My main AngularJS module is declared in a script tag near the bottom of my index.html page, and called at the top in the html element.

As far as my views are concerned, I have a pair of partial HTML forms which align with the PMIX Request and Response interactions, and a separate include file for the header, to reduce clutter. I may actually rename the controllers PMIXRequestCtrl and PMIXResponseCtrl, to make it obvious that is what they are. I'm used to HL7, where interactions have well-defined interactions. I like the alignment between controller and partial HTML view.

For the Saxon-CE piece, I have a  separate set of template views. I'm not as happy with these, but they serve a purpose. In the long run, both the HTML and XSLT views should be largely generated from the PMIX CAM schema. I have put these in the res directory because they are resources.

My approach is resource-based, whereas the PMIX data is really not. Three resources are represented in the PMIX payload: Patient, Prescription Report and Prescription. These are clipped out of the response message and then bound to the model scope in pmixResponse.html. This would be cleaner and more RESTful if the PMIX schema was broken into more granular interactions, but that's okay.

Monday, July 29, 2013

JSON vs. XML: Holy Wars and Container Elements

I've been working on a demo based on David Webber's CAM/Open-XDX demo for Prescription Medication Checking (PMIX). Open-XDX offers an easy way to set up a schema-based REST API for XML and JSON. I am building a mobile app with PhoneGap, AngularJS and Saxon-CE.

Originally, my demo mobile application used Saxon-CE with a bit of JQuery to coordinate Ajax calls. I soon replaced JQuery with AngularJS because I wanted a chance to use this framework, and because I liked the name "AngularSaxon". Meanwhile, I was also figuring out a way to embed a Firefox OS build within an Android PhoneGap build.

It soon became apparent that Angular, at 80K, could perform many tasks faster than Saxon-CE, at 800K, and since I had both JSON and XML available, I started shifting my focus, to allow a time trial between the two wire formats. One thing I discovered is that, whereas XSLT can handle something like:

   <Prescription id="1">...</Prescription> 
   <Prescription id="2">...</Prescription> 

...in the specific case where there is only one element, in JSON, this surfaces as the difference between an Array and an Object, which results in problems using Angular's ng-repeat directive. I was able to create a workaround in my JavaScript objects, as detailed below.

I had already created an Angular Service to handle rendering in both XSLT, using Saxon-CE, and in JSON. This Rendering Service already contained an exposed copy of the data returned from an API call, triggering an Angular Controller when the data is ready. I added the following method to the Rendering Service to insert an absent Array for a container element:

   renderingService.fixJSONContainer = 
      function(parentNode, childName) {
         if (parentNode !== undefined) {
            var childNode = parentNode[childName]
            if (!Array.isArray(childNode)) {
                parentNode[childName] = new Array(childNode)       
            }
            return parentNode[childName]
        }
        return []
    }


This helper method is available to the Response Controller, since it has already been Dependency Injected. In the Response Controller, I made the following changes to the render method for JSON:

   $scope.$on('renderJSON', function() {
    $scope.fixJSONContainers(renderingService.data)            

    $scope.pmix.resp.prescReport = renderingService.data[...]
    $scope.pmix.response.prescriptions =
       $scope.pmix.resp.prescReport['pmp:Prescription']
  });
         

  $scope.fixJSONContainers = function(data) {
     var prescriptionArray = 

        renderingService.fixJSONContainer(data[...], 
        'pmp:Prescription')
     for (prescriptionNode in prescriptionArray) {
        prescriptionDrugArray = renderingService.fixJSONContainer(

           prescriptionArray[prescriptionNode], 
           'pmp:PrescriptionDrug')
     }
  }


The local method fixJSONContainers is specific to my schema, and requires intimate knowledge of the schema; where for instance, the CAM elements have makeRepeatable. Other than that, this solution is generic. In my HTML View, Angular handles the data-binding using ng-repeat directives:
 
   <ol id="prescriptions">
      <li ng-repeat="prescription in pmix.response.prescriptions">
      <h3> Prescription #:
         {{prescription['pmp:PrescriptionNumberText']}}
         ({{prescription['pmp:DrugRefillNumberCount']}})</h3>
      <div ng-repeat="prescriptionDrug in 
          prescription['pmp:PrescriptionDrug']">
          <div> Prescription: 
              {{prescriptionDrug['pmp:DrugProductNameText']}}
              - {{prescriptionDrug['pmp:DrugStrengthText']}}
              - {{prescriptionDrug['pmp:DrugUnitOfMeasureText']}}
          </div>
       </div>
    </li>
 </ol> 
 
Once the changes have been made to the underlying Services and Controllers, the HTML View is very tight and concise, which is part of the magic of Angular. Autowired data-binding takes care of the rest.

Sunday, July 28, 2013

Open Mobile Web

It turns out AngularJS and it's companion UI framework bundles JavaScript support for Bootstrap, which is fantastic. All you need to do is include AngularJS, AngularUI, and the Bootstrap CSS, and you can say goodbye to JQuery for good, and start building Adaptive Design for the Mobile Web.

I really feel this piece has been lacking; I am very pleased with being able to nestle a Firefox OS app within a PhoneGap app, boosted by Angular. With the addition of Bootstrap, you really can have it all.

What is important here, though, is that all of these approaches intend to make themselves obsolete, leaving behind the promise of Firefox OS... Rich Internet Applications built on Open Web standards (HTML5, CSS), rather than Mono or Flash. In time, the best features of these frameworks will be built into the mobile browser.

Much as I love JavaScript and XSLT, there has to be a better way. I'm really starting to believe that a thin layer of Controller glue and maintainable AngularJS Services is this better way. This is a great time to be a mobile developer.

On the server-side, a resource-based Open Data REST API, Secured Mobile approach should allow us to build mobile applications that mash up resources across jurisdictions, securely and meaningfully.

Mobile Web and Mobile Exchange. This will be exciting.

Monday, July 15, 2013

JavaScript: The Cake and Eating it Too

In my previous post, I started to talk about some of the things I appreciate about Angular, and many of these things, I also like about technologies like Thymeleaf as a JSP replacement, Scala as a Java/Spring replacement, PhoneGap as a native mobile replacement... the list goes on, but what all of these have in common is that (with the exception of Scala, and I will get to that eventually) they leverage and enable the potential of HTML5 by using HTML5 as template and view, a purpose for which it is well suited. In short, these technologies are all  replacements for approaches that are harder to work with, and all come with a self awareness that their purpose is to make themselves obsolete as more standardized functionality comes built in the browser and server alike.

This makes me very happy, of course, because I am excited about the lightweight native mobile web approach promised by Firefox OS and other browser based platforms for the web and mobile. Why is this exciting? Because the developer community for native apps built in HTML5, CSS and JavaScript with a decent framework is huge. I would hazard a guess that Angular JavaScript could be taught in schools very easily, and deployed onto mobile devices, shared with other students using github... it's a good time to be exploring new technologies.

My own personal preference is a sort of best of breed client layer formed by layering Angular JS and then Saxon CE over Cordova (PhoneGap), which I have been referring to as "SaxonCord", although the more I use the functionality built into Angular, the less I rely on Saxon CE as a client layer. For some things, like SVG manipulation or working with XML messaging standards like HL7 CDA or NIEM, Saxon CE is a rockstar; however, these standards are becoming more open, and in doing so, have started to embrace JSON, at which point the autowired data binding Angular provides is really all you need to inject data into a page. I have used client-side Inversion of Control frameworks in Adobe Flex; Angular is just plain easier.